Every claim, checked
against six models.
Ask once and Keimodel runs your question across up to six models, then returns one answer broken into claims, each marked with the models that back it and the models that dispute it.
20 credits free, no card. Then $5 for 100 credits, and they never expire. There is no subscription.
The same prompt, five image models.
Give two image models the same words and they rarely picture the same scene. Switch to Image mode and Keimodel runs one prompt across all five at once, so you choose the frame instead of paying five times over to find it.
Create an image of a corner bakery at dawn, warm light spilling onto a wet street, shot on 35mm film.
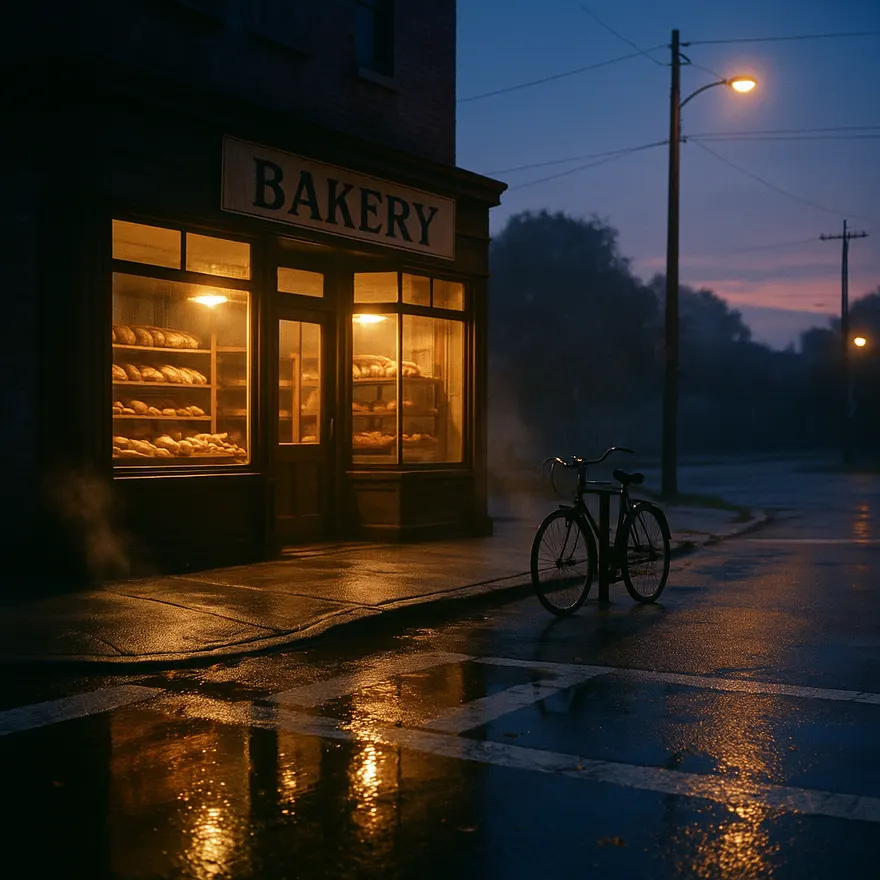
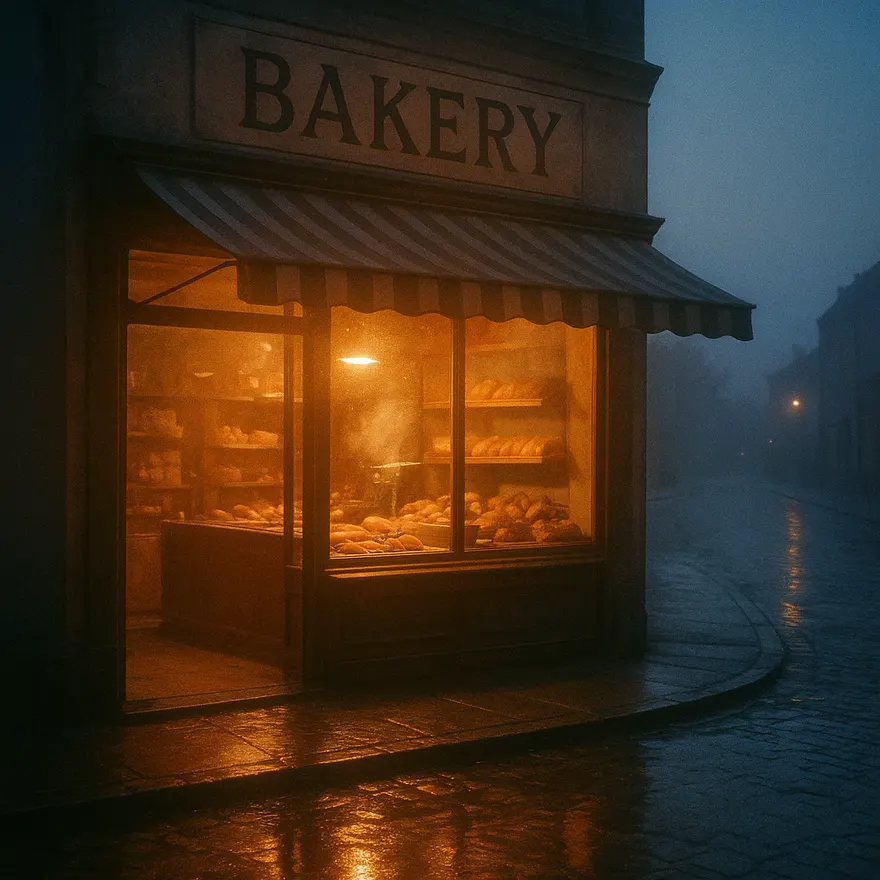
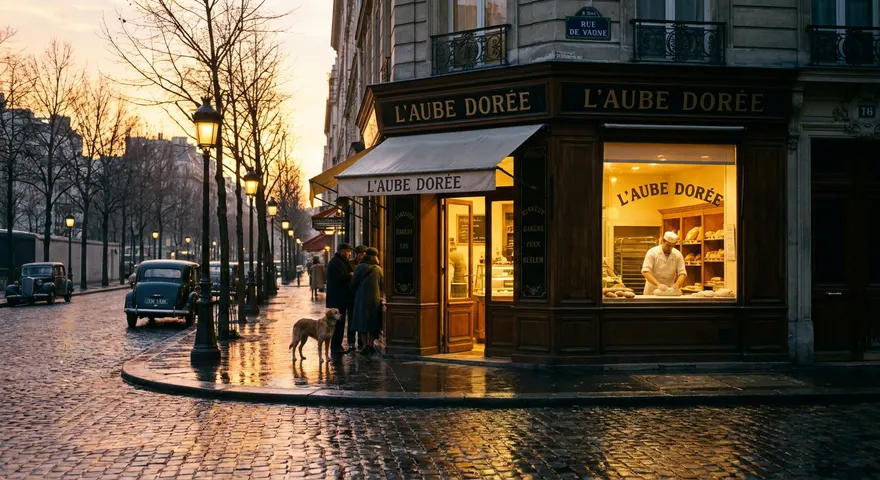
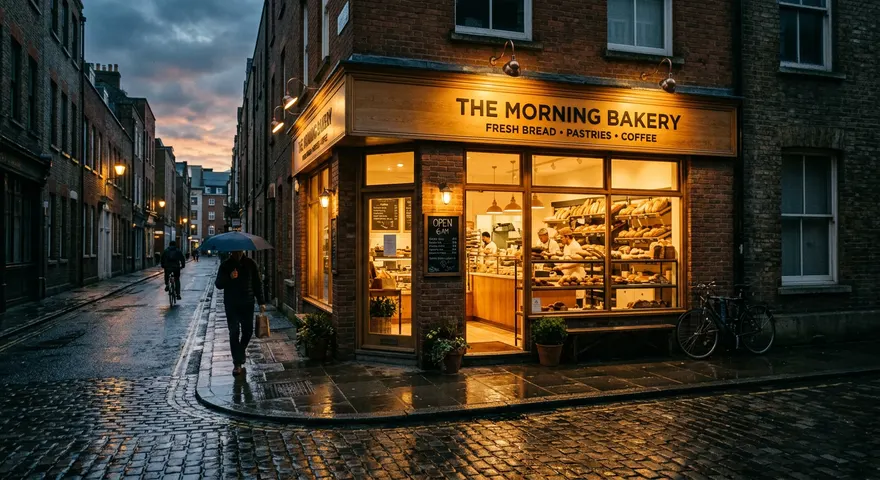
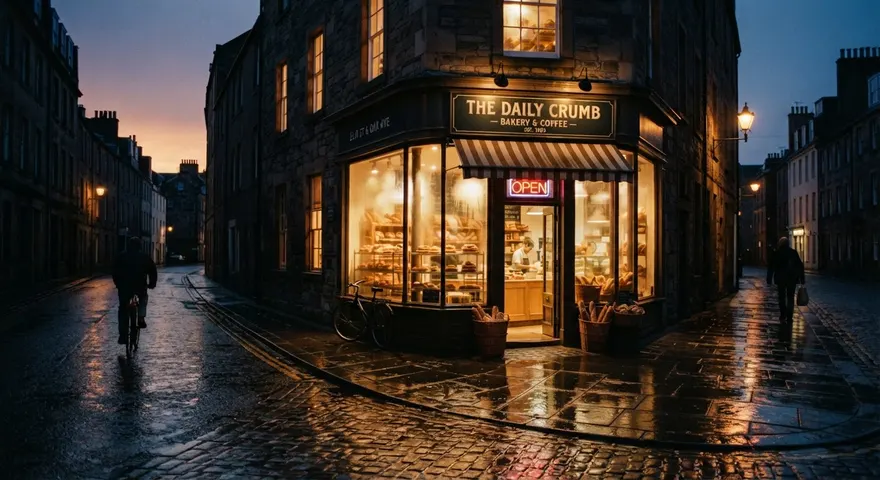
Five renders, one run
We ran these on 1 September 2026: one prompt, one run, the first result from each model, no retries and no edits. Two came back square and three came back widescreen from the same words, which is the reason to look at them side by side.
All five cost 12 credits together, about $0.48 on the $20 bundle.
Run your own promptThe verdict, claim by claim.
Keimodel reads every response and merges them into one answer, then splits that answer into its individual claims. Each one carries the models that support it and the models that dispute it, so a line every model backed and a line one model invented never look the same on the page.
Mostly aligned, but one date is contested.
Synthesized from 4 models
Consensus answer
The treaty was signed in 1648, ending the Thirty Years' War. Most models agree on the year; the disagreement is over the exact month.
Where they agree
- The treaty ended the Thirty Years' War
- It established state sovereignty norms
Where they diverge
The signing month
Claim agreement
Signed in 1648
Signed in October 1648
Llama places it in May, likely a hallucinated month.
Worth saying plainly: models that agree are not independent witnesses. They share training data and increasingly learn from each other, so they can converge on the same mistake. Six models disagreeing is a reliable signal to go look. Six models agreeing is weaker evidence than it feels like, and Keimodel is built to show you the first rather than sell you the second.
You pay for questions you ask. That is the whole model.
No plan, no seat, no monthly minimum, nothing to cancel. You buy credits once and they never expire, every model shows its cost before you run it, and we refund any run that does not finish.
Free
Try Keimodel with no commitment.
- 20 credits on sign-up
- The same models as the paid tiers
- No credit card required
Starter
$0.05 per credit
Top up when your free credits run low.
- 100 credits
- Access to all models
- Credits never expire
Pro
$0.04 per credit
Best value for regular users.
- 500 credits
- Access to all models
- Credits never expire
Max
$0.035 per credit
For power users running many comparisons.
- 1,000 credits
- Access to all models
- Credits never expire
1 credit = 1 model response · Most models cost 1-5 credits · The verdict is priced separately
Priced before you run
Every model carries its credit cost in the picker and its real input and output price per million tokens on the panel, and the total for the lineup you have built sits under the Run button. We meter nothing after the fact.
Or bring your own key
Add an OpenRouter key in Settings and every model response runs on your own account and costs you no credits at all. Only the verdict, the part that reads them all and marks up the claims, stays on ours.
What to ask six models.
Not every question. Ask one with a settled answer and all six agree, the confidence score reads high, and you have learned something small. The questions worth the credits are the ones where the models pull apart, and you can spot those by their shape rather than by their subject.
Judgment calls
Real tradeoffs, no single right answer. Models weight the tradeoffs differently and you get to see how.
Should we move a write-heavy service off Postgres to DynamoDB, or shard what we have?
Predictions
Nothing to look up, so each model reasons from a different prior. The spread is the useful part.
What breaks first if traffic on this architecture grows tenfold?
Edge cases
The place a confident single answer is most likely to be quietly wrong, and the place a dissenting model earns its keep.
How does a rounded tax total behave when line items are discounted after tax?
Fast-moving facts
Models train on different snapshots of the world, so on anything recent they know different things.
What changed in EU AI Act enforcement obligations this year?
Powered by every leading AI provider
Go beyond the chat
Playbooks for your job, guides for every workflow, and open models you can run yourself. The library behind the chat.
Copy-paste prompt playbooks for your exact job, from real estate to bookkeeping.
Step-by-step guides for running, building, and shipping with LLMs and agents.
Run open models on your own machine. Private, offline, and free to run.
Learn, compare, and go deeper
Guides, explainers, benchmark deep dives, and practical how-tos, built around the models you compare.
How to instrument LLM apps with OpenTelemetry
OpenTelemetry (OTel) is the vendor-neutral standard for distributed tracing. The GenAI semantic conventions extend it to LLM calls. This guide covers setting up OTel tracing for LLM applications, exporting to Jaeger or Grafana, and the GenAI conventions.
How to monitor and reduce LLM API costs in production
LLM API costs can grow unexpectedly as usage scales. This guide covers cost attribution, per-request tracking, anomaly detection, and practical techniques that reduce costs by 50-80% without sacrificing quality.
5 min readHow to test LLM prompts automatically with Promptfoo
Promptfoo is an open-source CLI for testing, evaluating, and comparing LLM prompts. This guide covers writing test cases in YAML, running evaluations, comparing models, and catching prompt regressions in CI.
6 min readHow to trace and debug LLM calls with LangSmith
LangSmith is LangChain's observability platform for logging, tracing, and evaluating LLM applications. This guide covers setup, automatic tracing, custom traces, and using the dashboard to debug production issues.
6 min readAsk the question you have been guessing at.
Six models, one answer, and a line under every claim saying who backed it. Your first 20 credits are on us, and there is nothing to cancel afterwards.